Indexing guide
Duplicate without user-selected canonical: how to fix it
Google found duplicate versions of a page and picked one itself, because you did not tell it which one.
ReadGoogle knows the page exists but has not crawled it yet. Here is how to change that.
If Google Search Console shows discovered currently not indexed for some of your pages, this guide explains what it means and how to fix it, step by step.
Discovered, currently not indexed means Google found the URL but has not crawled it yet, often to avoid overloading your server or because it does not see the page as a priority. Speed up your server, link to the page from important pages, keep it in your sitemap and cut low-value URLs.
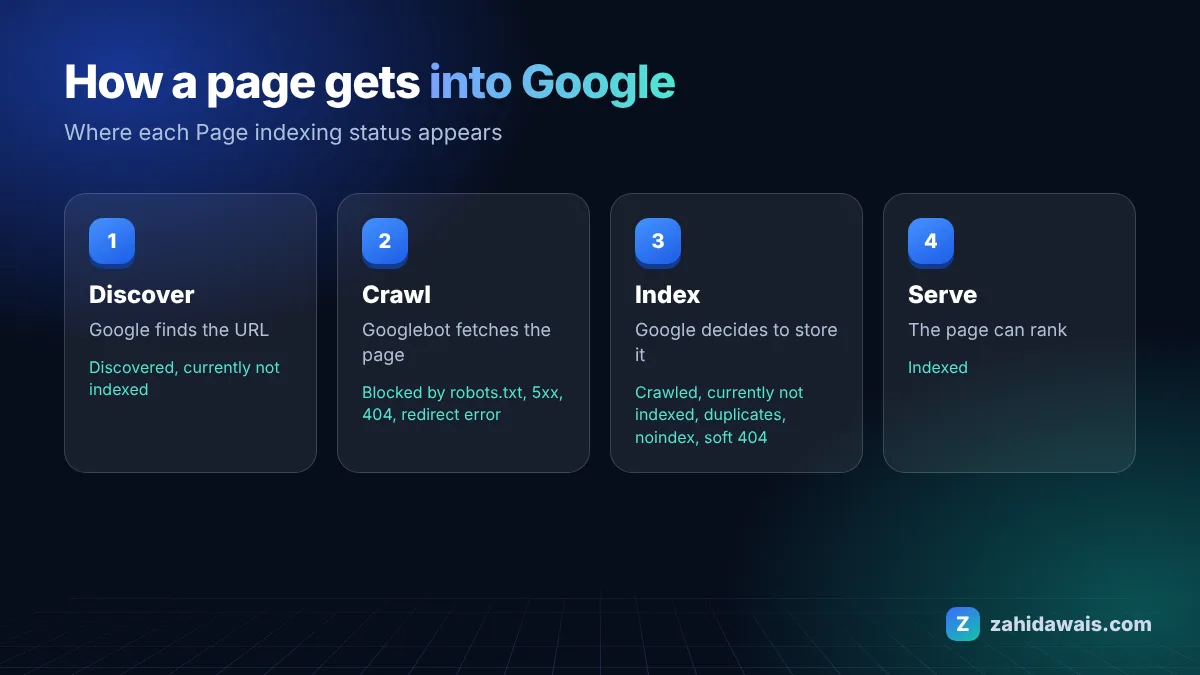
The Search Console Page indexing report help says Google found the page but has not crawled it yet, usually because crawling the site was expected to overload it, so the crawl was rescheduled. It also notes it can take time for Google to find and crawl new pages.
These are the most common causes I see when auditing client sites:
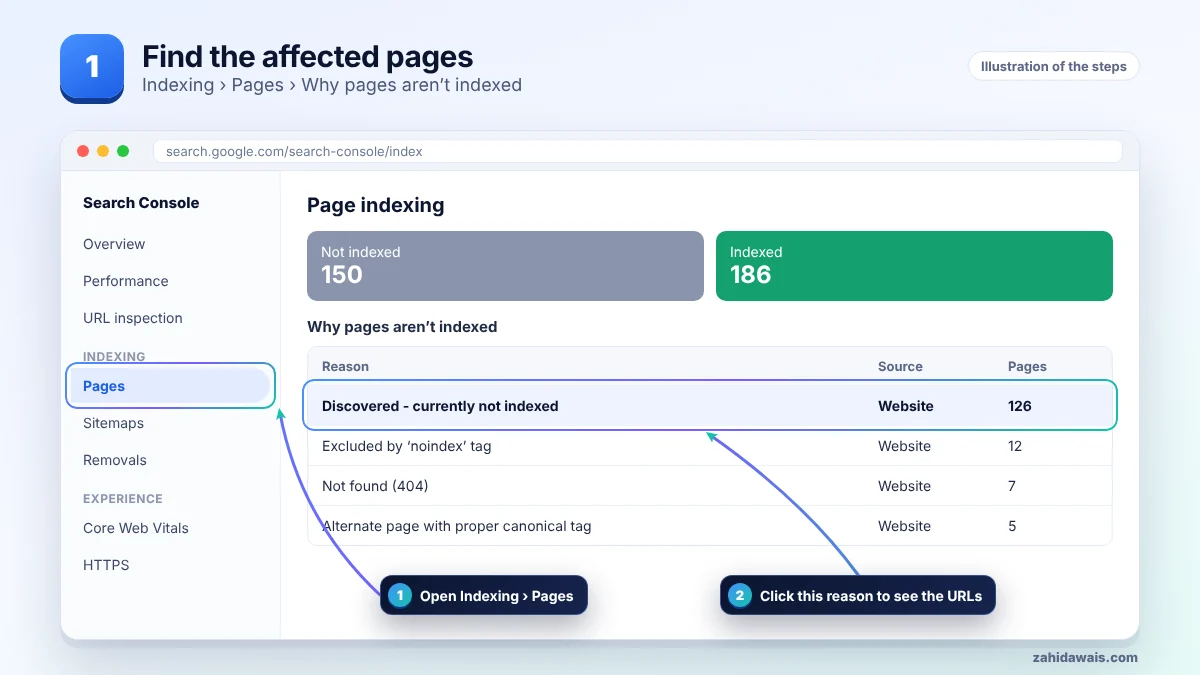
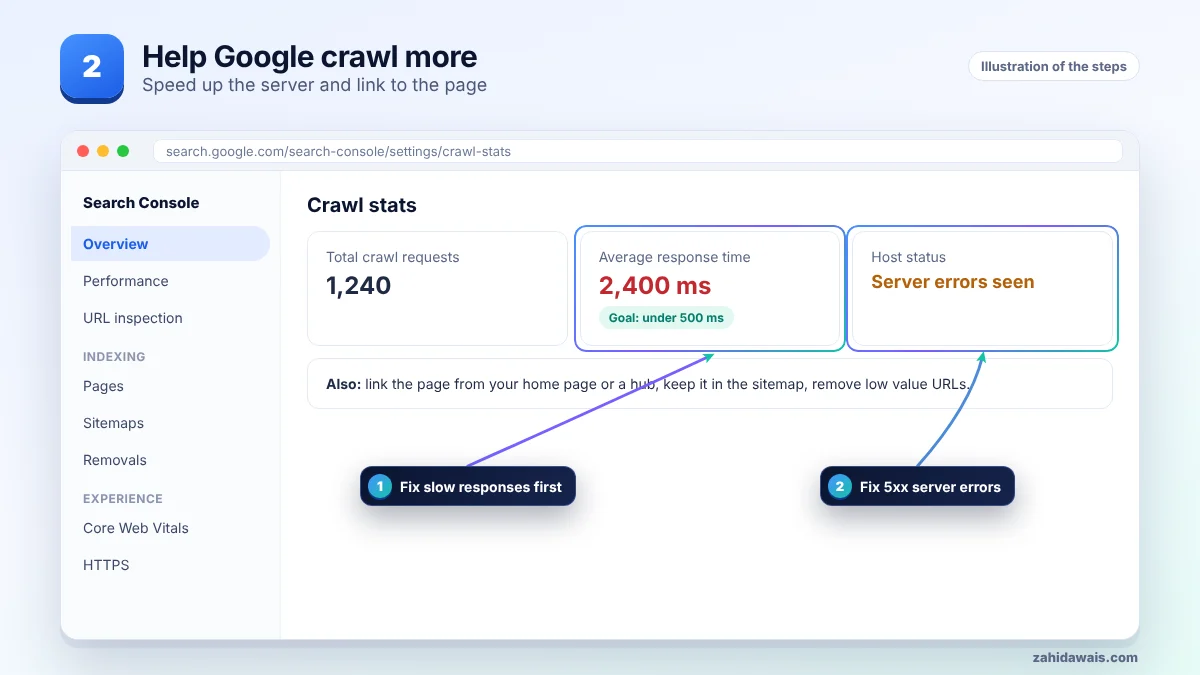
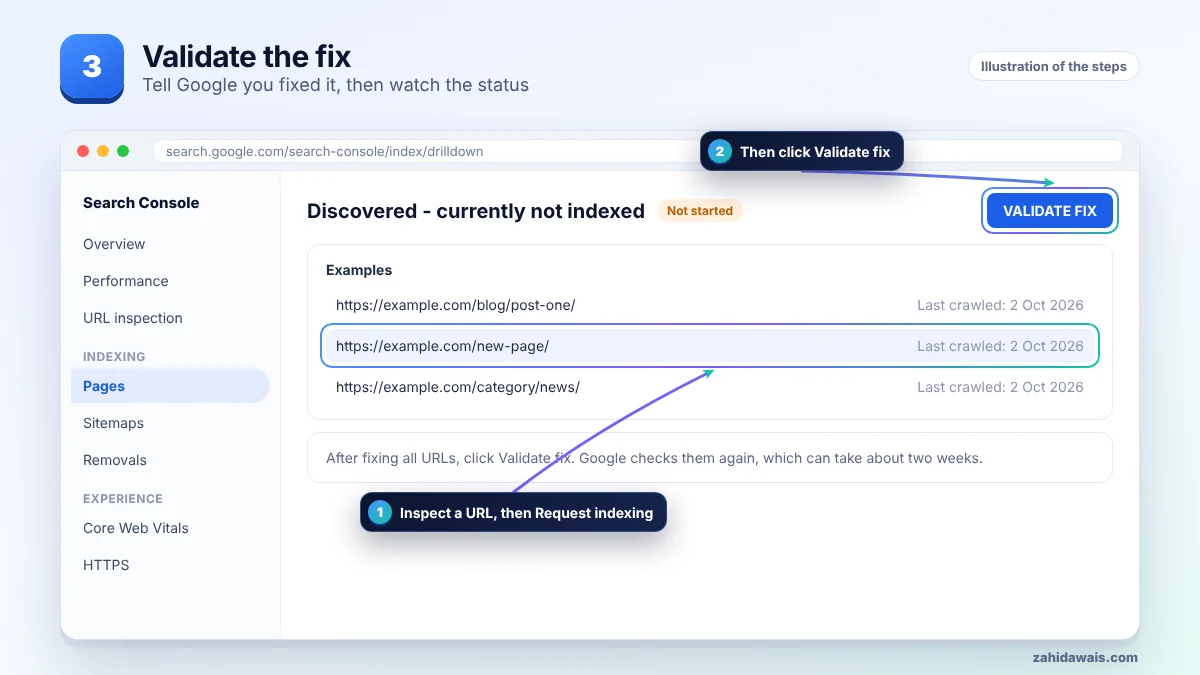
First find the affected URLs in Search Console, then work through the steps in order and stop when the issue is solved. The pictures show each stage.
| What to check | Where | What you want to see |
|---|---|---|
| Server errors | Settings, Crawl stats, Host status | No recent problems |
| Response time | Crawl stats, average response time | Stable or falling over time |
| Internal links | Links report, top linked pages | The page is linked from important pages |
| Low value URLs | Pages report and Crawl stats by file type | Few parameter, filter or search URLs crawled |
A site published 126 location pages in one day on shared hosting. They all showed discovered, currently not indexed, and Crawl stats showed slow responses. After moving to faster hosting, linking the 20 most important pages from a hub, and removing 60 near-empty pages, Google began crawling the rest over the next weeks.
If your Crawl stats show many server errors or very slow responses, fix hosting first. Google’s Google guide to HTTP status codes and soft 404s explains that 5xx errors make Google slow down crawling.
Not sure which pages are affected or why? My technical SEO service starts with a free audit, and the free SEO checklist covers the basics.
It varies from days to months. Faster servers, better internal links and fewer low-value pages usually shorten the wait.
A sitemap helps Google discover pages, but internal links and server health matter more for getting them crawled.
No. This status is about crawl priority, not a penalty.
Google says the Indexing API is only for job posting and livestream pages. Use URL Inspection for other pages.
Yes. Publishing many pages at once, or having lots of low-value URLs, spreads Google’s crawl attention thin.
Discovered means not crawled yet. Crawled means Google visited and decided not to index for now.
Facts checked on 8 October 2026 against these official pages. Read how I check facts in my editorial policy and disclaimer.
Google found duplicate versions of a page and picked one itself, because you did not tell it which one.
Read
The page says “OK” to Google but looks empty or like an error. Here is how to fix that.
Read
Google found a URL that sends visitors somewhere else. Most of the time that is fine. Here is how to tell.
ReadSend your website and I will reply with a free audit.