Indexing guide
Discovered, currently not indexed: causes and fixes
Google knows the page exists but has not crawled it yet. Here is how to change that.
ReadGoogle visited your page but chose not to add it to the index yet. Here is why, and what to do.
If Google Search Console shows crawled currently not indexed for some of your pages, this guide explains what it means and how to fix it, step by step.
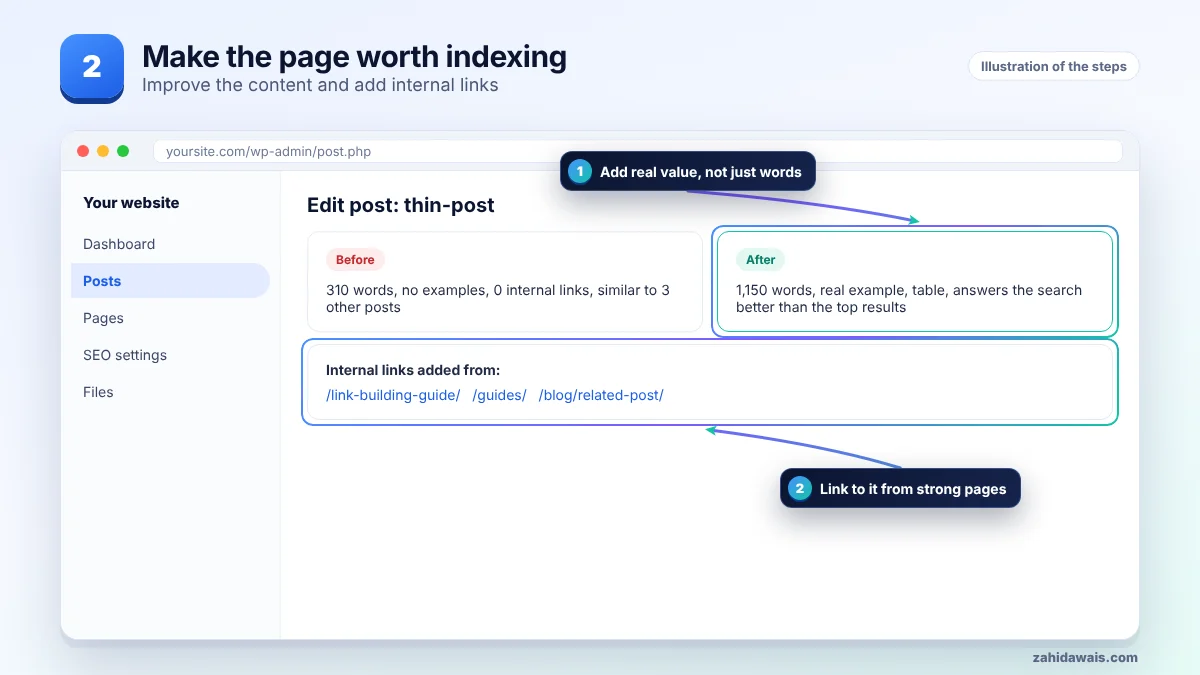
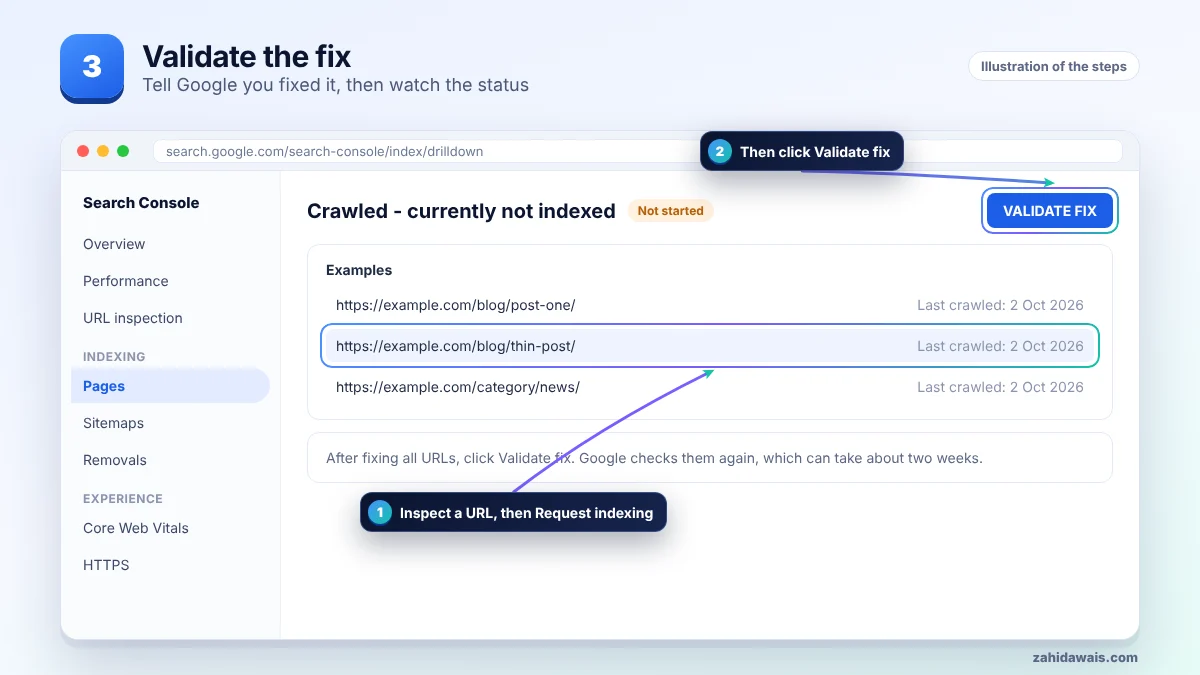
Crawled, currently not indexed means Googlebot visited the page but decided not to index it for now. It is usually a quality or value signal, not a technical error. Improve the content, add internal links from strong pages, remove near-duplicates, then use URL Inspection to request indexing.
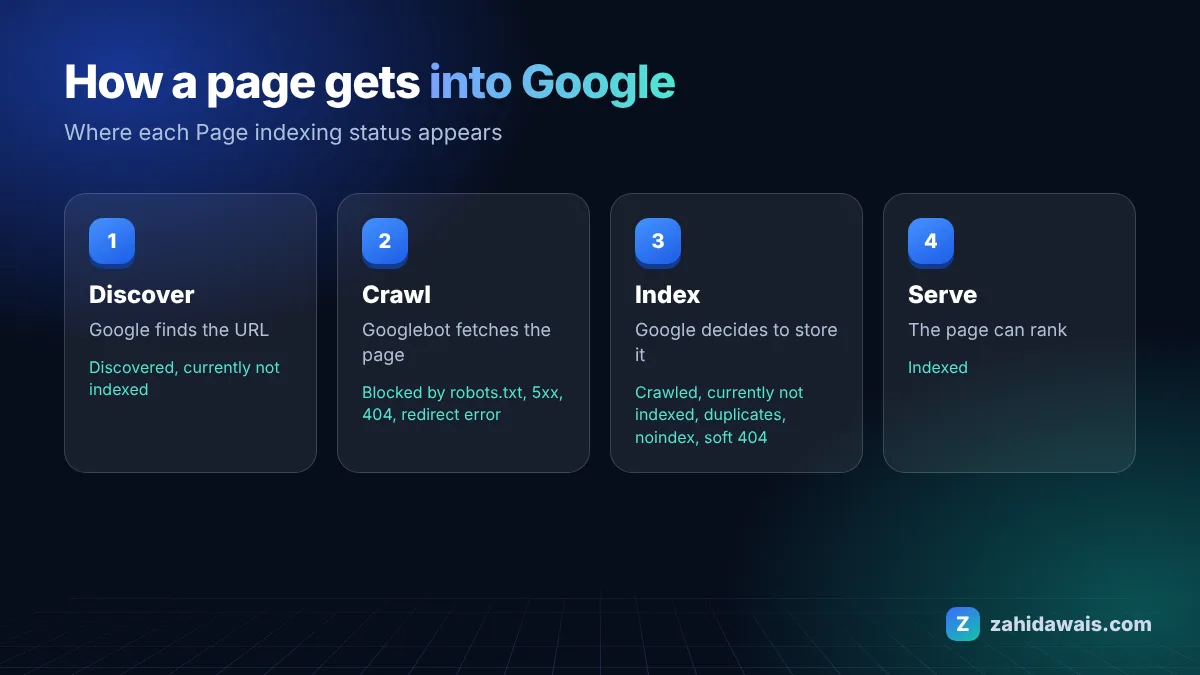
In the Search Console Page indexing report help Google explains that the page was crawled but not indexed, may be indexed in the future, and that there is no need to resubmit the URL for crawling.
These are the most common causes I see when auditing client sites:
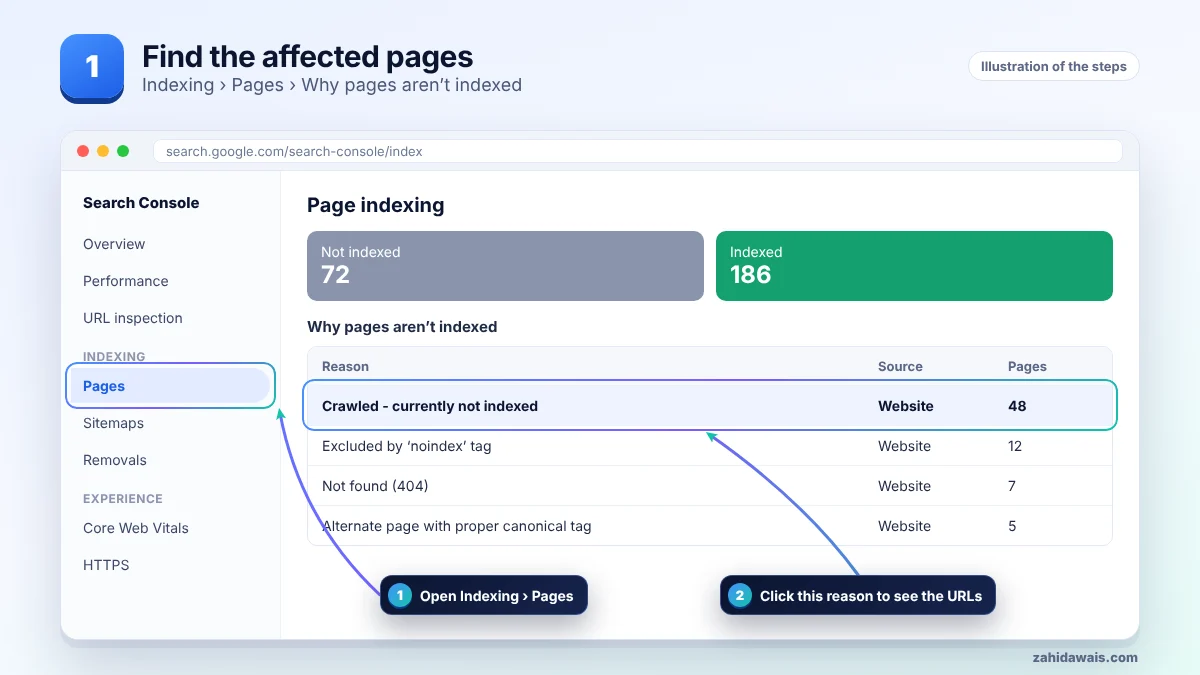
First find the affected URLs in Search Console, then work through the steps in order and stop when the issue is solved. The pictures show each stage.
| Check | Weak page (often not indexed) | Strong page (more likely indexed) |
|---|---|---|
| Value | Repeats what other pages say | Adds an example, data or a clear answer |
| Duplication | Very similar to other URLs on the site | Clearly different topic and intent |
| Internal links | Only in the sitemap or a tag page | Linked from related, indexed pages |
| Search match | Topic nobody searches for | Answers a real query people type |
A blog had 48 tag pages listed as crawled, currently not indexed. Each one only showed two or three post excerpts. Instead of requesting indexing 48 times, the tag pages were set to noindex and the 6 most useful topics became real hub pages with an intro, a table and links to every post. The hubs were indexed, and the noindexed tags left the report.
If hundreds of pages show this status, the cause is usually sitewide: too many thin pages. Fix the template or prune weak pages instead of resubmitting.
Not sure which pages are affected or why? My technical SEO service starts with a free audit, and the free SEO checklist covers the basics.
Not exactly. It is a status. Google crawled the page and decided not to index it for now, usually because of content value or duplication.
There is no fixed time. Improved pages are often indexed within days to a few weeks, but some never are if Google sees them as low value.
No. Google says there is no need to resubmit. Request once after a real improvement, then wait.
Yes, relevant links and internal links help Google find and value a page, which can lead to indexing.
Only if they have no value. Otherwise improve or merge them. Delete truly useless pages and return a 404 or redirect them.
No. Discovered means Google has not crawled the page yet. Crawled means it visited but chose not to index it.
Facts checked on 8 October 2026 against these official pages. Read how I check facts in my editorial policy and disclaimer.
Google knows the page exists but has not crawled it yet. Here is how to change that.
Read
Google found duplicate versions of a page and picked one itself, because you did not tell it which one.
Read
The page says “OK” to Google but looks empty or like an error. Here is how to fix that.
ReadSend your website and I will reply with a free audit.